TraceNest
Turn production errors into searchable, code-linked incident timelines for engineering teams. Connect logs, deploys, and pull requests to speed up debugging.
What is TraceNest?
TraceNest is a production error intelligence platform that turns application errors into searchable, code-linked incident timelines. It connects logs, deployments, and pull requests so engineering teams can move from “something broke” to “here is what changed, who owns it, and what to investigate next.”
The product idea targets a common operational problem: production debugging is rarely slowed down by a lack of data. It is slowed down by data scattered across monitoring tools, source control, deployment systems, and team conversations. Engineers may find an error in one tool, a deploy record in another, and the relevant code change in a pull request. TraceNest would bring those signals together in a single workflow.
The opportunity is not simply to create another error tracker. TraceNest can differentiate itself by making the incident timeline the center of the debugging experience. Instead of presenting an error as an isolated event, it can show the sequence of relevant events around it: when the error began, which release was active, what code changed, which logs share the same trace or request, and how the issue evolved.
For teams evaluating production error tracking software, TraceNest’s promise is straightforward: reduce the time engineers spend assembling context before they can begin fixing a problem.
The problem TraceNest solves
When a production error occurs, an engineer typically needs to answer several questions:
- What is failing?
- When did the failure start?
- Which users or services are affected?
- What changed shortly before the issue appeared?
- Which logs, traces, or code changes are connected to it?
- Who should investigate or resolve it?
These answers are often distributed across separate systems. An error tracking product may show a stack trace, an observability platform may contain the relevant logs, and a deployment tool may record the release. Source control can show the code changes, but only after an engineer finds the right commit or pull request.
This creates a context-switching tax. Engineers spend time searching, copying identifiers, comparing timestamps, and asking teammates for details instead of diagnosing the failure directly.
The cost is not limited to developer time. Slow incident investigation can also contribute to:
- Longer customer-impacting outages
- More interruptions for senior engineers
- Repeated investigation of known problems
- Unclear incident ownership
- Poor handoffs between on-call responders and feature teams
- Reduced confidence in releases
TraceNest should focus on eliminating the investigative work between detection and understanding. It does not need to replace every monitoring, ticketing, or source-control system. It needs to connect them well enough to make the next debugging action obvious.
Target audience for production error intelligence
TraceNest should begin with a specific audience rather than trying to serve every organization that operates software.
Primary audience: growing software teams
A strong initial customer profile is a product or platform team that:
- Runs customer-facing software in production
- Ships changes frequently
- Has several engineers or services
- Already uses error tracking, logs, or deployment tooling
- Does not have a dedicated reliability engineering team for every service
- Feels that debugging takes too long because context is fragmented
These teams have enough operational complexity to experience the problem regularly, but may not have the budget or appetite for a large observability platform migration.
Secondary audience: engineering leaders
Engineering managers, directors, and technical leads care about the operational outcomes behind the product:
- How long issues remain unresolved
- Whether incidents are repeatedly assigned to the same people
- Which services produce the most actionable errors
- Whether recent releases correlate with new error patterns
- How effective the team’s on-call and ownership processes are
TraceNest can serve these needs with useful summaries and workflow analytics, but it should avoid becoming a broad engineering-management dashboard before the core debugging workflow works.
Potential early adopters
The best early adopters are likely to be teams that already feel pain and can describe it precisely. Examples include:
- Startups with a small on-call rotation
- SaaS companies with multiple services and frequent releases
- Agencies or product studios supporting several client applications
- Teams migrating from a monolith to distributed services
- Engineering groups using several observability and deployment tools
- Teams that have outgrown chat-based incident coordination
Who is not an ideal first customer?
TraceNest may be a poor fit initially for teams that have no production telemetry, deploy infrequently, or do not have a repeatable incident process. It may also be difficult to sell to highly regulated organizations before the product can demonstrate robust access controls, data retention policies, auditability, and deployment options.
A focused launch should prioritize teams with an existing telemetry stack and a clear need to connect the information they already collect.
Market opportunity and product gap
The broader observability category includes products for error tracking, metrics, logs, traces, incident response, and application performance monitoring. Established tools can provide deep telemetry and powerful query capabilities. Source-control and deployment platforms provide detailed records of code changes and releases.
The product gap TraceNest can explore is the space between those systems: helping engineers understand how an error relates to a release, code change, log sequence, and service owner.
This is a product hypothesis, not a guarantee that existing tools cannot do these things. Many platforms offer integrations, release markers, correlation features, or incident workflows. TraceNest needs to prove that its particular combination is easier to use and more valuable for the target customer.
A useful discovery process is to interview teams about the last three incidents they investigated. Ask:
- Which tools did they open?
- What information did they need but could not find quickly?
- How did they connect an error to a release or pull request?
- Which parts of the process required manual copying or searching?
- Where did the investigation stall?
- What information was missing from the post-incident review?
- What existing integration or dashboard almost solved the problem?
These interviews can expose whether the real opportunity is correlation, search, ownership, timelines, or another workflow entirely.
Why the incident timeline matters
A timeline provides a familiar way to organize operational events. It can bring together:
- Error occurrences and changes in error volume
- Deployment and rollback events
- Pull request merges
- Related log records
- Trace or request identifiers
- Ownership changes
- Incident status updates
The timeline should not be a feed of everything the connected systems produce. It should be a focused explanation of events that may be relevant to a particular error or incident. Good relevance and clear filtering are more important than sheer event volume.
TraceNest’s core features
TraceNest’s initial feature set should prioritize the path from error discovery to useful investigation. Avoid building a broad observability suite before validating that this workflow is valuable.
Searchable error groups
Individual events often represent repeated instances of the same underlying failure. TraceNest should group related errors and provide a searchable index based on fields such as:
- Error message and exception type
- Service, environment, and release
- First and most recent occurrence
- Event count and affected users, when available
- Stack trace or fingerprint
- Status, owner, and priority
Search should support practical queries, such as finding errors by service, release, date range, or error text. Filters should be understandable without requiring users to learn a specialized query language on day one.
Code-linked incident timelines
The central TraceNest experience should show a chronological view of evidence related to an error. For example:
- Error volume increases after a deployment.
- A particular release becomes active.
- A pull request included in that release modifies the affected module.
- Related logs show a specific request or dependency failure.
- The issue is assigned to the service owner.
The interface should distinguish observed facts from possible explanations. “The error began after release 2.8.1” is a timing observation. “Release 2.8.1 caused the error” is a causal conclusion that requires stronger evidence.
Deployment and pull request correlation
TraceNest should connect releases to source changes through reliable identifiers such as commit SHAs, release names, repository names, and deployment timestamps. Integrations should display the evidence behind a connection so users can judge its relevance.
A useful first release does not need to support every source-control provider and deployment platform. It should support the tools used by the initial customer segment, then expand based on observed demand.
Log and trace context
Logs can provide details that an error event does not include. TraceNest should make it easy to move from an error to related log records, ideally using stable identifiers such as trace IDs, request IDs, or service and time-window combinations.
This is also an area where data quality matters. If a team’s logs do not include consistent correlation identifiers, TraceNest should say so rather than presenting weak matches as definitive connections.
For teams adopting common telemetry conventions, OpenTelemetry documentation is a useful reference for understanding traces, metrics, logs, and instrumentation practices.
Ownership and incident workflow
Correlation is valuable, but engineers also need to act. TraceNest can support lightweight workflows such as:
- Assigning an owner or team
- Marking an error as investigating, resolved, or ignored
- Adding investigation notes
- Linking an error to an incident
- Recording a suspected or confirmed resolution
- Notifying the appropriate channel or responder
The product should integrate with existing issue trackers and communication tools rather than forcing teams to duplicate their entire workflow inside TraceNest.
Useful summaries without opaque automation
Automated summaries can reduce time spent reading long event histories, logs, and stack traces. They should be presented as assistance, not as unquestionable diagnosis.
A trustworthy summary should:
- Link back to its source events
- Separate facts from hypotheses
- State when evidence is incomplete
- Avoid claiming that a code change caused an error without adequate support
- Allow engineers to inspect the underlying telemetry
This approach can make future AI-assisted debugging more useful while maintaining a clear line between evidence and generated interpretation.
Competitive advantage and positioning
TraceNest will compete indirectly and directly with error tracking platforms, observability suites, incident management tools, and internal dashboards. Customers may already have some degree of error-to-release correlation in their current stack.
The product should therefore avoid positioning itself as “another place to view logs.” A sharper position is:
TraceNest connects production errors to the operational and code changes that help engineers investigate them.
That positioning is specific enough to guide product decisions and messaging.
| Evaluation area | Typical fragmented workflow | TraceNest opportunity |
|---|---|---|
| Error discovery | Errors appear in a tracking tool | Keep error groups searchable and actionable |
| Release context | Release details live elsewhere | Place deployment events beside error history |
| Code investigation | Engineers search source control manually | Link relevant commits and pull requests |
| Log investigation | Logs require a separate search | Surface related log context when identifiers permit |
| Incident handoff | Context is copied into chat or tickets | Preserve investigation context in a shared timeline |
The table describes a potential product advantage, not an assertion that every competitor lacks these capabilities. TraceNest should compare itself against the actual tools used by prospective customers and make precise, verifiable claims.
A defensible product advantage
The strongest advantage is unlikely to be a single integration. Integrations can often be reproduced. A more durable advantage could come from combining:
- High-quality event correlation
- A timeline designed around investigation
- Fast, low-friction setup
- Clear service and team ownership
- Trustworthy links to source evidence
- Learning from how teams resolve recurring errors
Over time, TraceNest could become more useful as it builds a reliable map of services, releases, owners, error patterns, and resolution history. That advantage depends on data quality, customer trust, and workflow adoption—not just data volume.
Recommended technology stack
TraceNest is a data-intensive SaaS product, so its architecture should support secure ingestion, fast search, and clear separation between customer workspaces. The best stack depends on the founding team’s expertise and the expected scale. The following is a practical starting point, not a requirement.
Frontend and application layer
A TypeScript-based web application can provide a productive foundation for a complex, interactive incident interface. React is a mature option for building the frontend, while Next.js can support routing, server rendering, and application-level development patterns.
Use a component system that makes dense operational interfaces easy to scan. Prioritize:
- Fast navigation between errors and related events
- Keyboard-accessible search and filters
- Clear timestamps and time-zone handling
- Useful loading and empty states
- Responsive layouts for incident review, even if desktop is the primary experience
The trade-off is that a feature-rich frontend can become complicated quickly. Keep the first product focused and avoid building a custom visualization framework unless real user needs require one.
API and ingestion services
Use a backend stack the team can operate confidently. TypeScript, Go, or another strongly supported server language can work. Separate interactive API requests from asynchronous ingestion and correlation jobs where necessary.
The ingestion path should handle:
- Authentication and tenant identification
- Schema validation
- Rate limits and payload size limits
- Idempotency and duplicate events
- Retryable processing failures
- Data redaction rules
- Per-customer usage accounting
A robust ingestion service matters because an error intelligence platform becomes least trustworthy when it loses, delays, or misattributes the events customers depend on.
Storage and search
A practical early architecture could include:
- PostgreSQL for organizations, users, permissions, projects, integrations, ownership, and product metadata
- Object storage for larger raw payloads, subject to retention and privacy rules
- A search or analytics store when query volume and event volume justify it
- A queue for asynchronous processing and integration syncs
PostgreSQL documentation is a useful starting point for relational data design. For event search, a dedicated engine may eventually improve high-volume queries, but it adds operational complexity. Avoid adopting multiple databases before benchmarks show that the primary store cannot meet the product’s latency and cost goals.
Queueing and background work
Background jobs can process incoming events, update error groups, sync deployment metadata, and build timeline relationships. A managed queue can reduce operational overhead, while a self-managed system may offer more control at scale.
Important design properties include retries, dead-letter handling, backpressure, and observability into processing lag. The product team should be able to distinguish “no related logs exist” from “the log correlation job is delayed.”
Observability for TraceNest itself
TraceNest must monitor its own ingestion and processing pipeline. Track service health, ingestion latency, queue depth, dropped or rejected events, integration failures, and search latency. Dogfooding the product can help the team discover missing workflows, but it does not replace independent reliability testing.
Security and tenancy
Security should be part of the initial architecture, not a later enterprise add-on. Consider:
- Tenant isolation at the application and data-access layers
- Role-based access controls
- Encryption in transit and at rest
- Secure storage and rotation of integration credentials
- Audit events for sensitive administrative actions
- Configurable data retention
- Data export and deletion procedures
- Redaction of secrets and personal information
For organizations with strict requirements, clarify what data TraceNest stores, how long it is retained, and which subprocessors or services handle it. Do not promise certifications or compliance outcomes until they have been independently achieved and verified.
Monetization strategies
TraceNest can test several pricing models. The right choice should reflect customer value while keeping usage understandable.
Usage-based pricing
A common approach is to price by event volume, data retention, or a combination of ingestion and retention. This aligns price with infrastructure costs, but can create uncertainty if customers cannot predict their telemetry volume.
To make usage-based pricing more predictable:
- Include a meaningful free or trial allowance
- Show current usage and projected charges
- Provide configurable notifications
- Offer sampling and filtering controls
- Explain which data counts toward the bill
Per-seat pricing
Per-seat pricing is easy for buyers to understand and can align with team collaboration. However, it may discourage broad adoption if the product is most valuable when responders, developers, and managers can all access the same incident context.
A hybrid model can charge for data volume while including a generous number of collaborators.
Tiered plans
A tiered SaaS model can separate plans by scale and capabilities:
- Starter for small teams validating the workflow
- Growth for multiple services, integrations, and longer retention
- Business for advanced access controls, audit history, and team-level administration
- Enterprise for negotiated security, support, and deployment needs
Tiers should represent meaningful customer outcomes rather than arbitrary feature gates.
Design partner pricing
Early design partners can help validate the product and reveal integration requirements. A discounted or time-limited agreement can be reasonable, but the team should still test willingness to pay. Strong enthusiasm without budget commitment is not enough to establish product-market fit.
Risks and mitigation
Integration complexity
Connecting error events, logs, releases, and source-control records is difficult because each system uses different schemas and identifiers.
Mitigation: Start with a small set of integrations. Define a canonical internal event model, preserve source metadata, and show users how each relationship was established. Build additional connectors in response to repeated customer demand.
Weak or misleading correlation
A release may happen near an error spike without causing it. If TraceNest implies causation from timing alone, engineers will lose trust.
Mitigation: Label correlations accurately, show the underlying timestamps and data, and distinguish observed relationships from inferred explanations. Let users inspect or dismiss suggested connections.
Sensitive data exposure
Logs and error payloads can contain credentials, personal information, or proprietary data.
Mitigation: Provide redaction controls, minimize retained payloads, document data handling clearly, and support customer-configured retention. Treat security review as part of product development from the beginning.
Alert and event overload
A timeline that includes every event can reproduce the same noise that already exists in monitoring systems.
Mitigation: Group repeated events, prioritize meaningful changes, offer filters, and let teams customize what appears. Measure whether users reach a useful next step faster, not just how much data the product ingests.
Competition from established platforms
A customer may already have a platform that offers error tracking and release correlation.
Mitigation: Position TraceNest around a specific investigation workflow. Validate whether customers value a dedicated cross-tool timeline enough to add another product. If existing products solve the problem well for the target audience, refine the target segment or product scope.
Data scale and infrastructure cost
High-volume telemetry can create rising storage and query costs.
Mitigation: Model cost per customer, offer sampling and retention controls, distinguish hot from archived data where appropriate, and benchmark query patterns early. Pricing should reflect the actual cost drivers without surprising customers.
Long sales cycles
Security reviews, procurement, and integration requirements can slow adoption, especially for larger organizations.
Mitigation: Begin with teams that can adopt independently, make setup straightforward, and build enterprise controls according to validated demand. Do not let large-company requirements obscure whether the core product is useful to smaller teams.
Measuring whether TraceNest works
The product should be evaluated against customer outcomes, not only sign-ups or event volume.
Useful product metrics include:
- Time from error detection to first useful investigation action
- Time from investigation start to confirmed owner
- Percentage of errors with a relevant release or code link
- Percentage of users who return to the incident timeline
- Number of manual context switches reported by users
- Integration setup completion rate
- Time to first correlated event after setup
- Weekly active teams and retained paid accounts
A north-star metric might measure how often a team uses TraceNest to reach a meaningful investigation outcome, such as assigning an owner, linking a likely change, or resolving an error. Define that metric carefully so that activity does not get mistaken for impact.
For formal claims about reduced resolution time, use a transparent measurement method. Compare defined time periods or matched incident types, explain limitations, and avoid attributing improvements to TraceNest alone when other process changes occurred.
Actionable implementation steps
Interview teams before building integrations
Talk to engineers and engineering leads about recent production incidents. Ask them to demonstrate their actual workflow, including the tools they opened and the information they had to copy manually. Document recurring friction rather than collecting feature requests in isolation.
Choose a narrow initial customer segment
Select a segment with a clear operational problem, an existing telemetry stack, and a short path to adoption. For example, focus on small SaaS engineering teams using a particular error tracker and source-control provider.
Define a minimum viable investigation workflow
Specify the smallest end-to-end experience that can prove the idea: ingest or import an error, group related events, connect it to a release, show relevant source changes, and assign an owner. Keep other features out of the first release unless discovery shows they are necessary.
Build a dependable data model
Create a canonical representation for errors, services, environments, releases, commits, logs, and timeline events. Preserve original source identifiers and make correlation confidence visible. Design tenant boundaries and retention policies before storing customer data.
Pilot with design partners
Work closely with a small number of teams. Observe setup, monitor processing quality, and review real incidents together. Ask whether TraceNest changed the investigation process—not simply whether users like the interface.
Measure outcomes and refine positioning
Track time to useful context, integration reliability, and repeated use. Compare customer feedback against the initial hypothesis. If the strongest value is deployment correlation, make that the product’s center. If ownership or handoff proves more valuable, adapt accordingly.
Expand carefully
Add integrations, retention options, collaboration features, and higher-scale capabilities based on demonstrated demand. Keep the product’s promise focused on making production errors easier to understand and act on.
The TraceNest opportunity
TraceNest has a promising product direction because it addresses a practical engineering problem: production context is often split across tools, while incident investigation requires that context to be understood together.
Its success will depend on more than the number of integrations it supports. The product must establish reliable relationships between errors, deployments, logs, and code; make those relationships easy to inspect; and help teams take a meaningful next step without overstating what the data proves.
The clearest initial USP is a searchable, code-linked incident timeline that brings relevant production and delivery context together. That creates a focused foundation for testing demand, building trust, and expanding into broader error intelligence over time.
For founders building the product, TurboStarter can help accelerate the SaaS foundation so more development effort can go toward TraceNest’s differentiated ingestion, correlation, and incident investigation experience.
Frequently asked questions
Production error intelligence connects application errors with relevant operational context, such as logs, deployments, code changes, ownership, and incident history. The goal is to help engineers investigate and resolve issues with less manual searching.
A traditional error tracker may focus primarily on capturing and grouping exceptions. TraceNest’s proposed focus is connecting those errors to a broader timeline of related releases, pull requests, logs, and investigation actions. The exact differentiation must be validated against the capabilities customers already use.
Not initially. A more practical strategy is to complement the tools teams already depend on and provide a focused layer for connecting their data. Replacing established monitoring infrastructure would increase adoption friction and broaden the product scope.
The first version should prove one end-to-end workflow: searchable error groups, release context, relevant code links, a focused incident timeline, and basic ownership. Add other integrations and automation only after customer use validates the need.
More ⚡ Productivity Tool SaaS ideas
Discover more innovative productivity tool SaaS ideas that are trending in 2026. Each idea is AI-generated with market validation and growth potential to help you find your next profitable venture faster than competitors.
Your competitors are building with TurboStarter
Below are some of the SaaS ideas that have been generated and built with our starter kit.
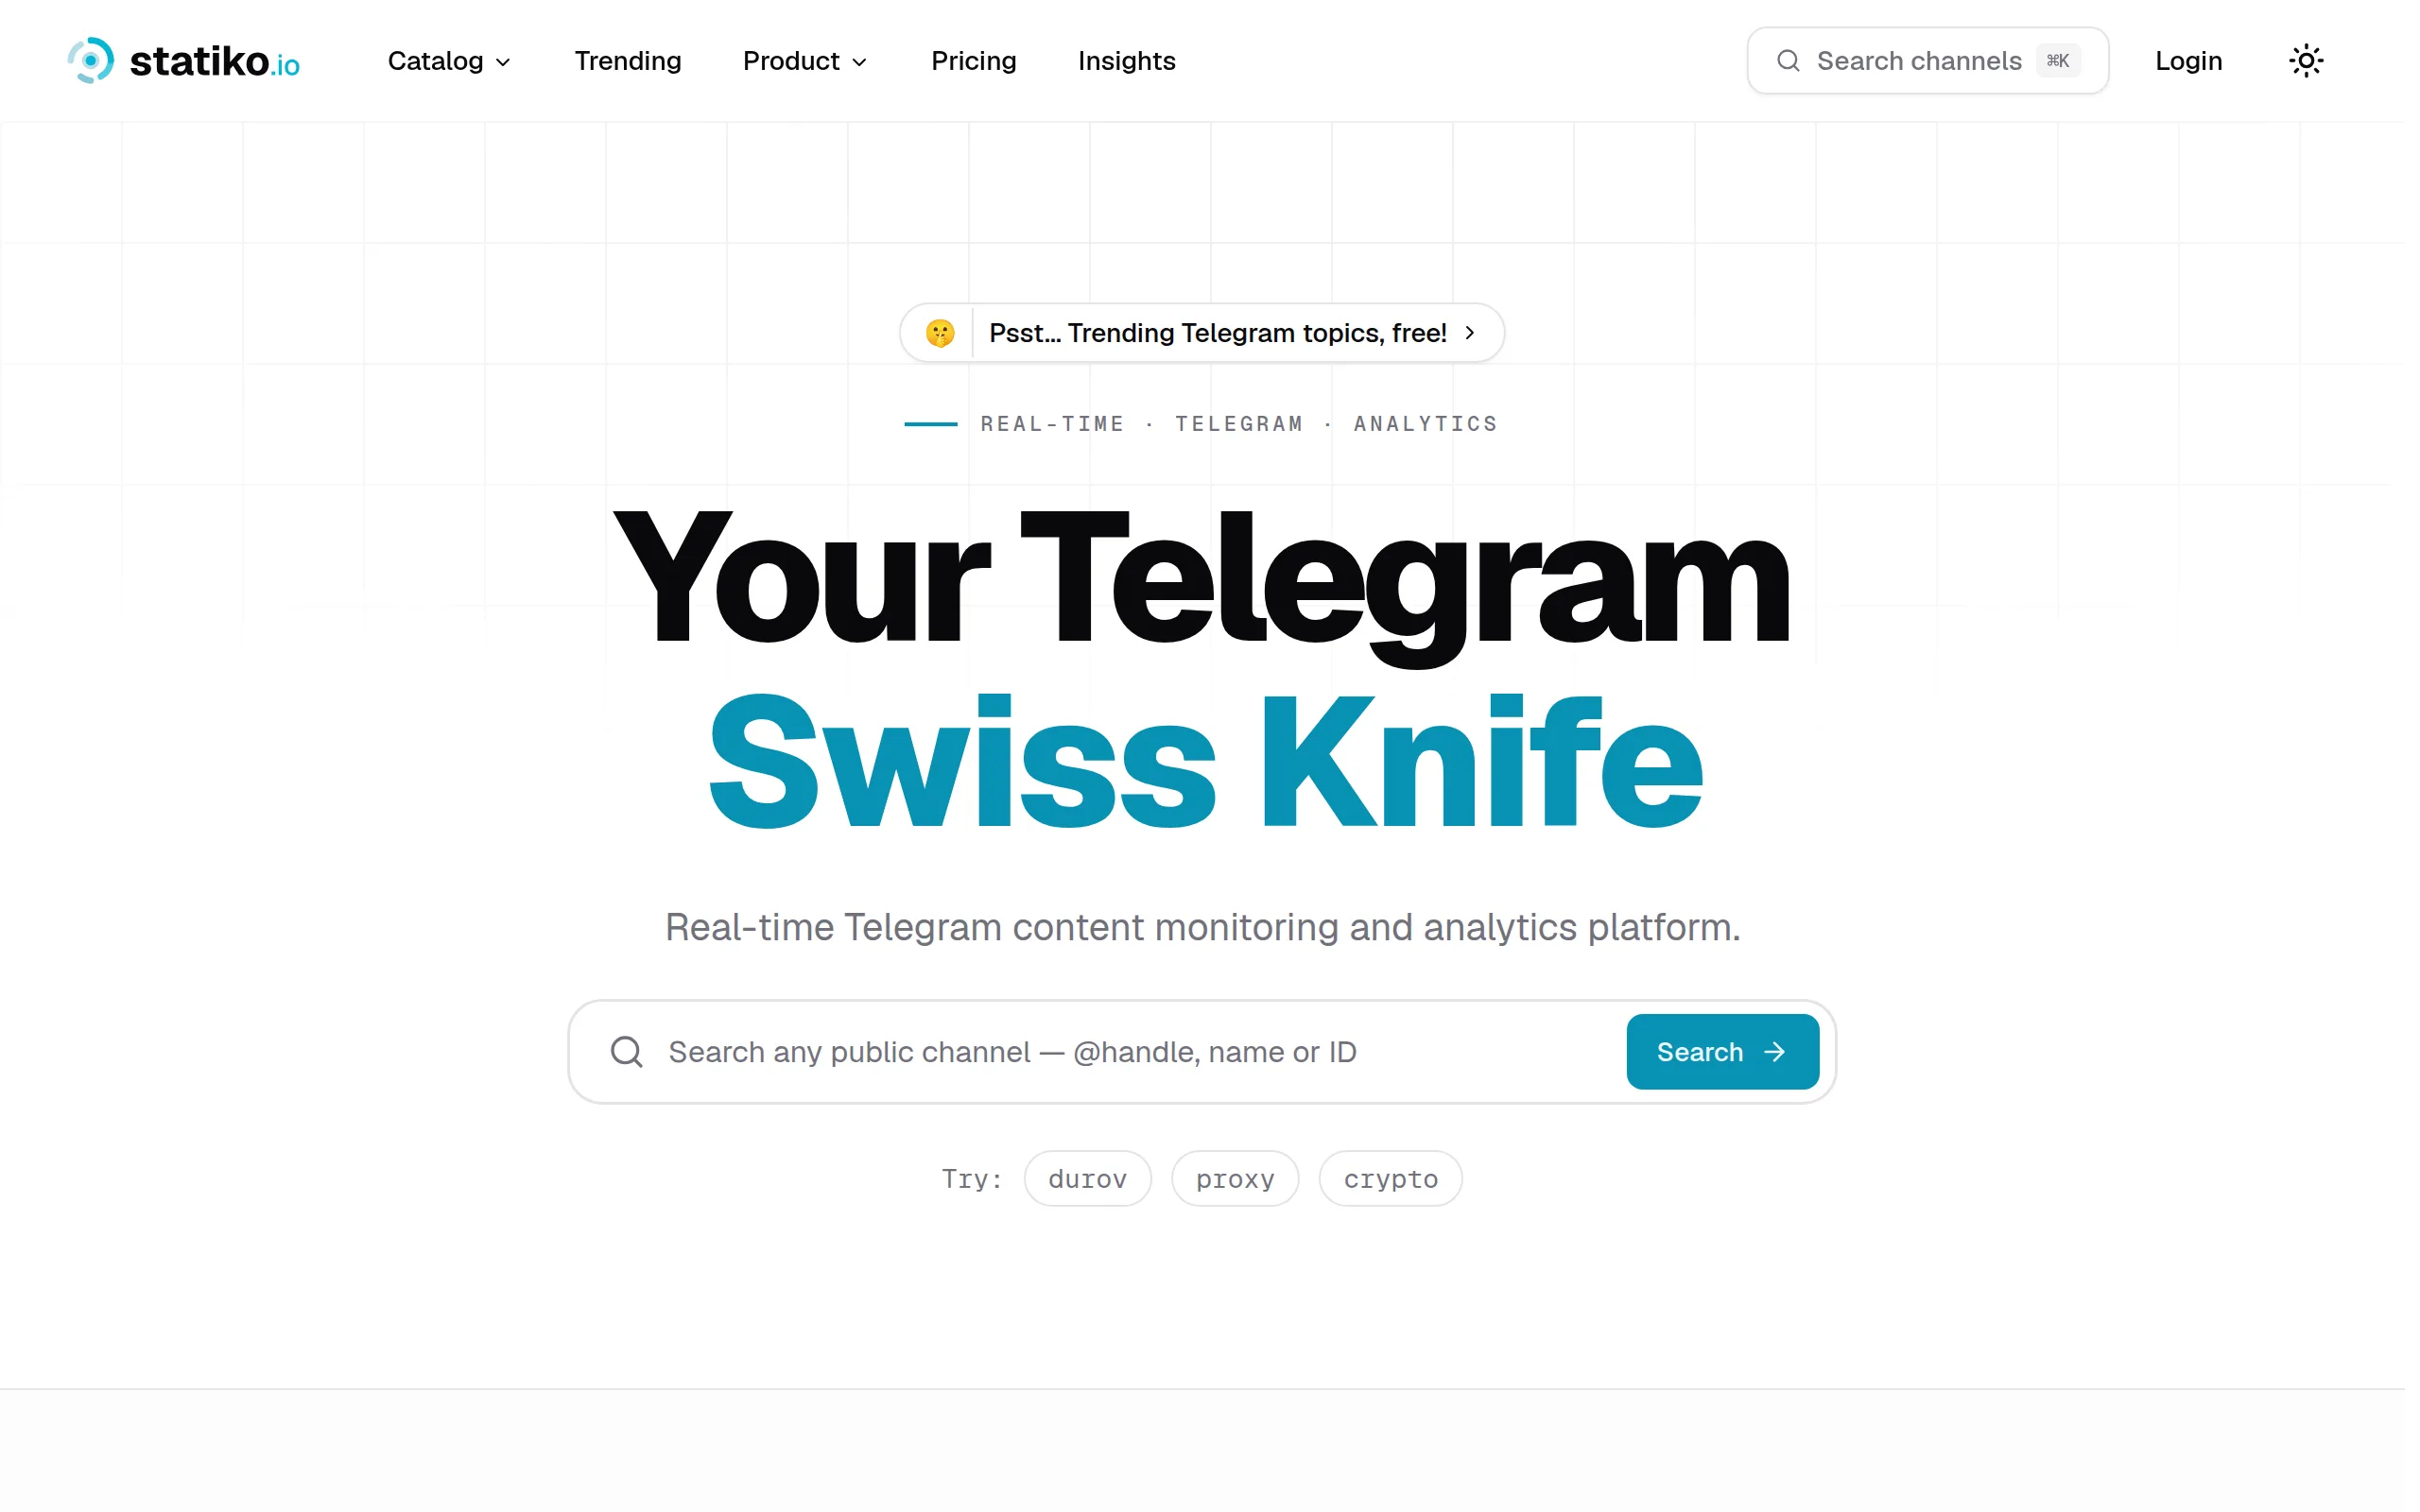
Statiko
Monitor any Telegram channel in real time - track posts, edits, deletions, and growth with AI recaps 📡
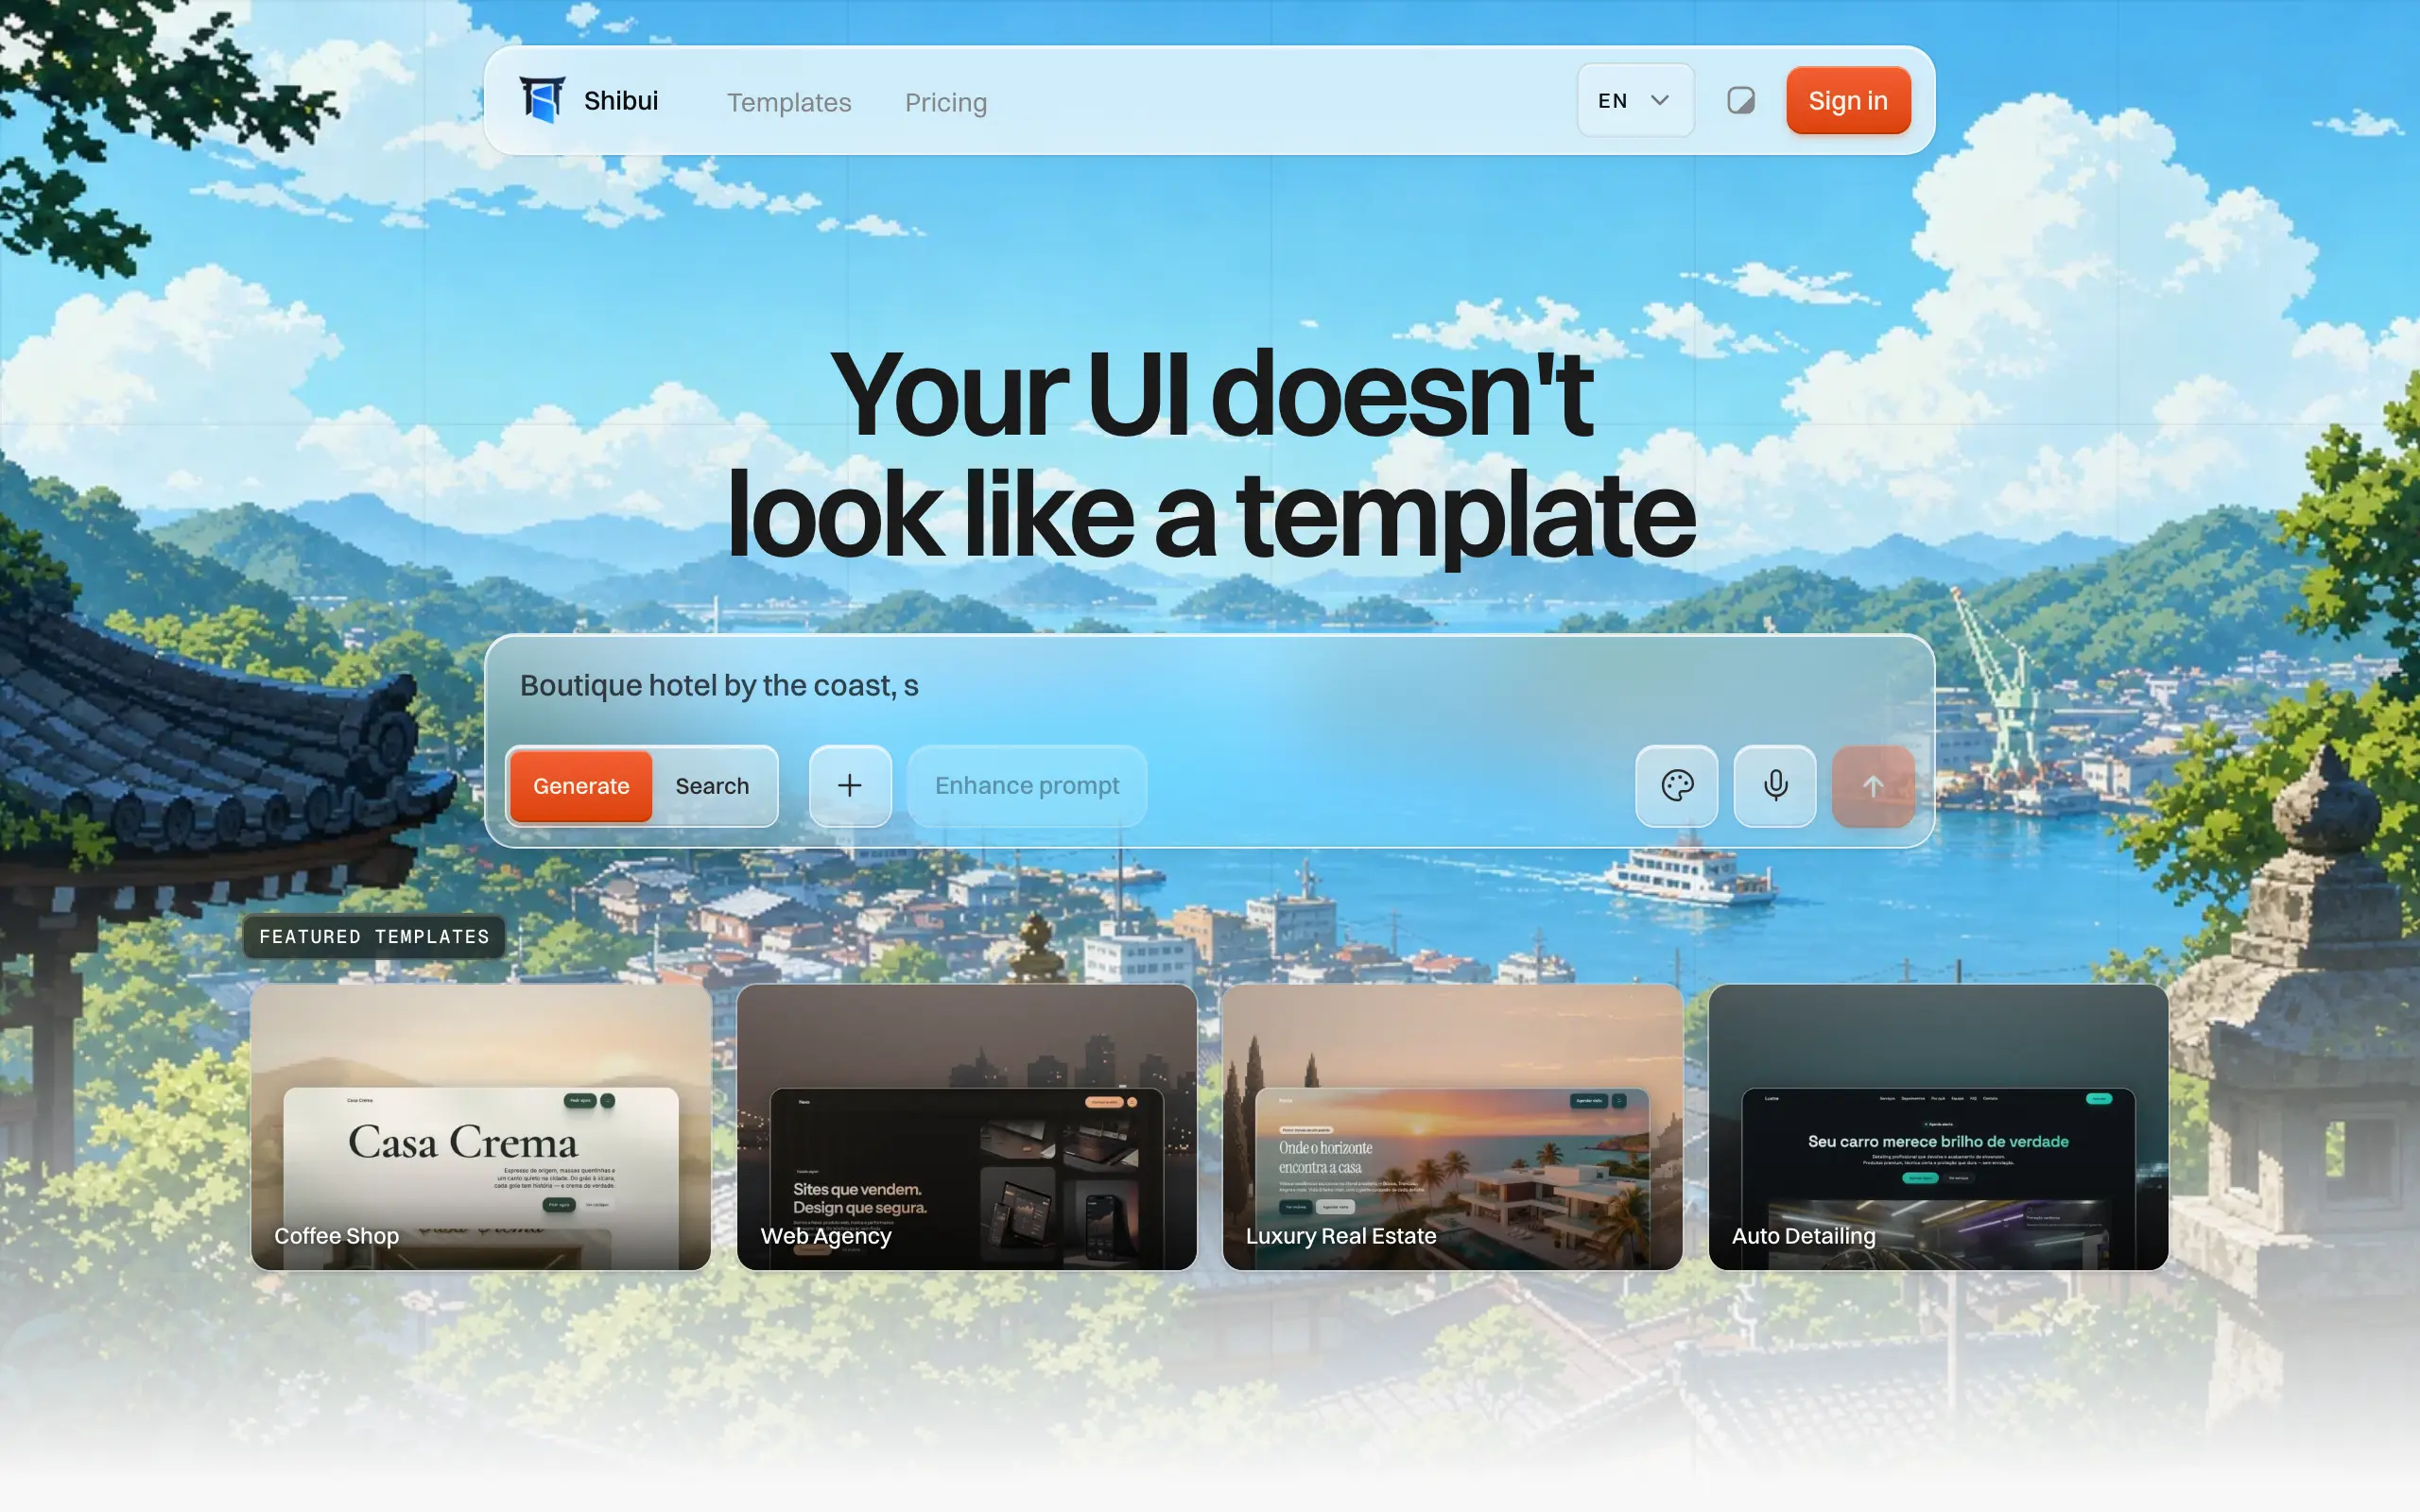
Shibui
AI website builder - describe your business, pick a niche template, edit by chatting, and publish instantly ✨
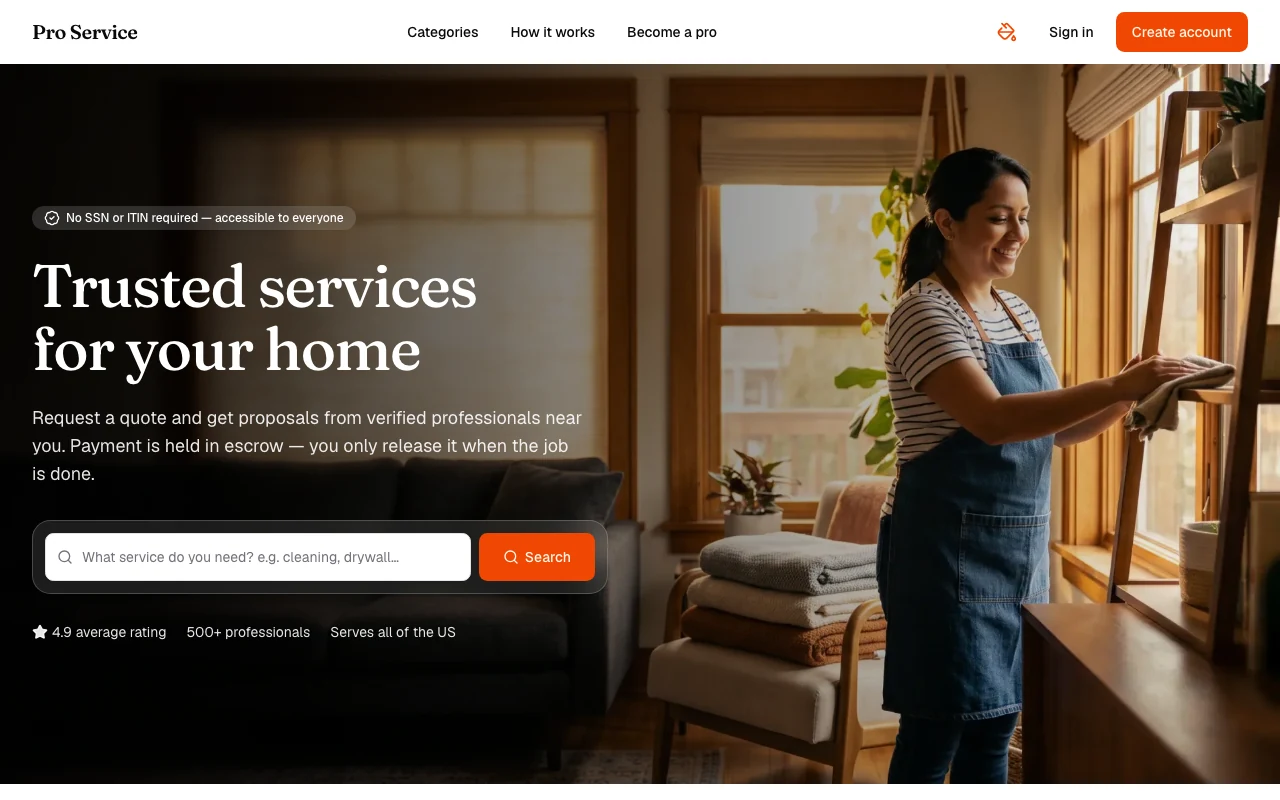
Pro Service
Find verified home service professionals, compare quotes, and pay securely through escrow - built for Brazilians across the US 🏠
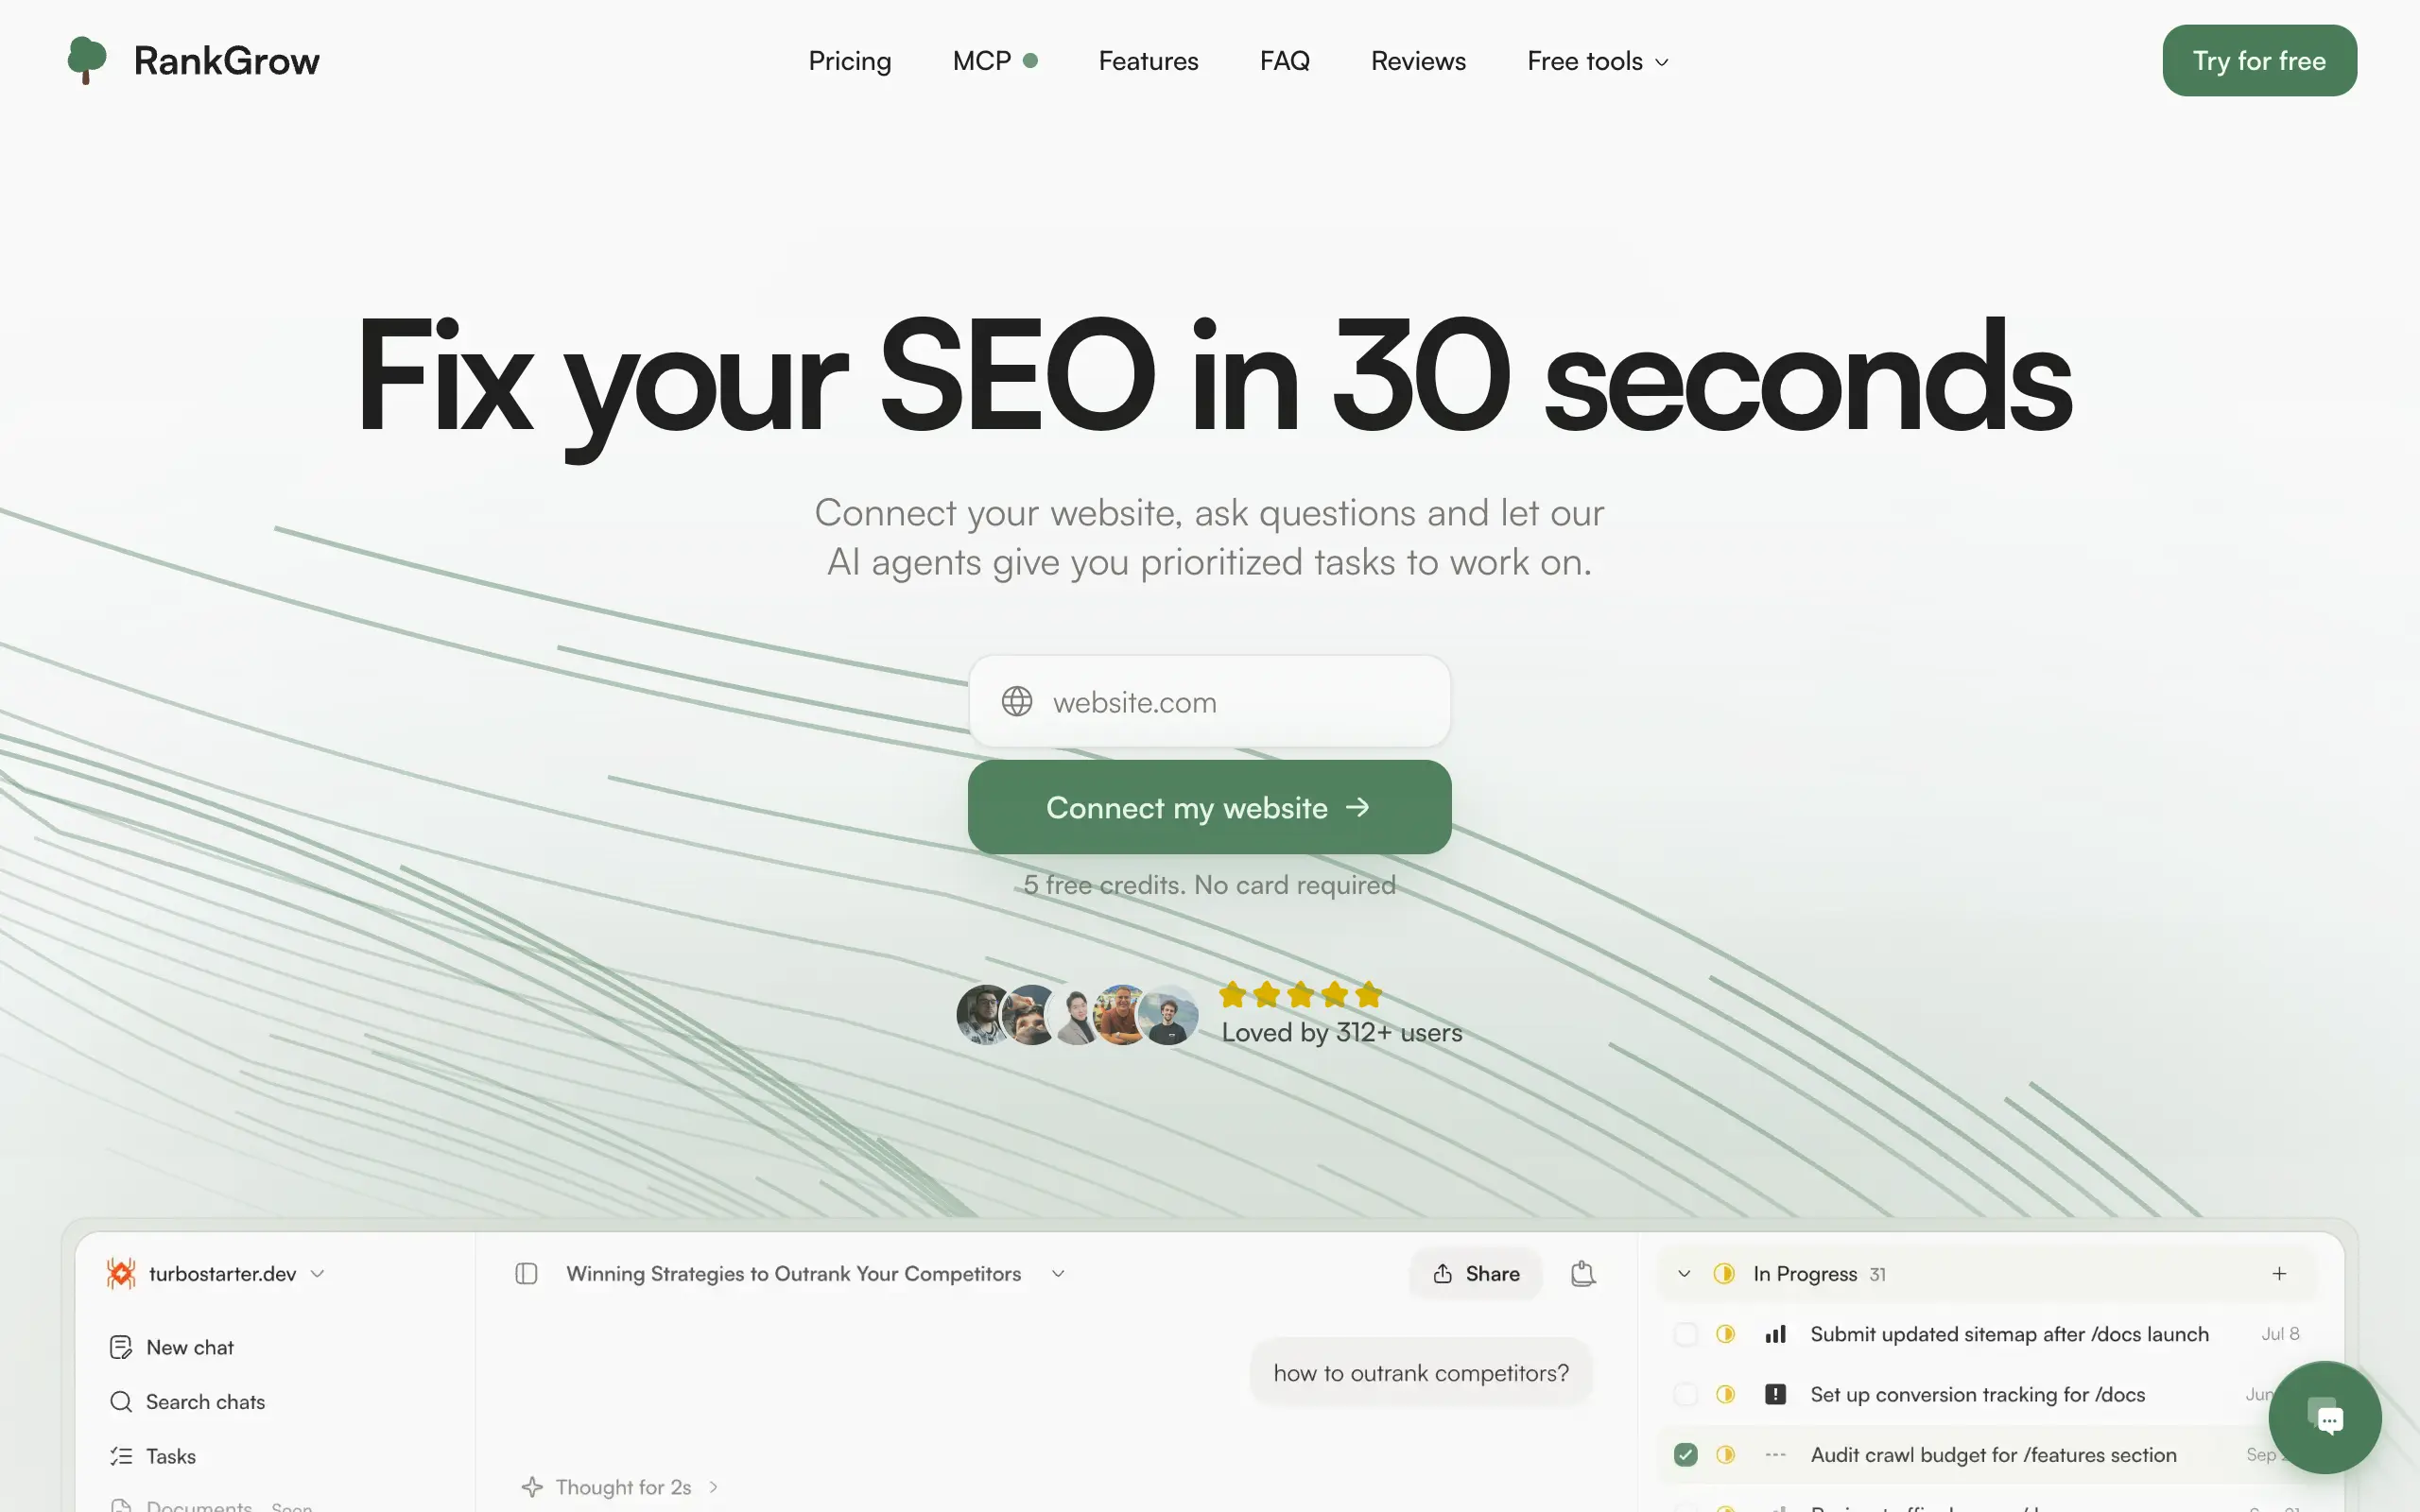
RankGrow
Fix your SEO with AI agents - connect Search Console, get prioritized tasks, and grow organic traffic 📈
SyncReads
Sync your favorite content for distraction-free reading, save time and replace multiple apps. Anytime, anywhere 🔄
Socialcrawl
Get clean, structured data from 21 platforms like TikTok, Instagram, and YouTube with a single request 📊
Statiko
Monitor any Telegram channel in real time - track posts, edits, deletions, and growth with AI recaps 📡
Shibui
AI website builder - describe your business, pick a niche template, edit by chatting, and publish instantly ✨
Pro Service
Find verified home service professionals, compare quotes, and pay securely through escrow - built for Brazilians across the US 🏠
RankGrow
Fix your SEO with AI agents - connect Search Console, get prioritized tasks, and grow organic traffic 📈
SyncReads
Sync your favorite content for distraction-free reading, save time and replace multiple apps. Anytime, anywhere 🔄
Socialcrawl
Get clean, structured data from 21 platforms like TikTok, Instagram, and YouTube with a single request 📊
Dotallio
Personalized AI apps that automate research, data extraction, and content creation without code 🤖
Talk to Santa
Enjoy a magical live video chat or receive a unique AI-generated video greeting from Santa Claus 🎅
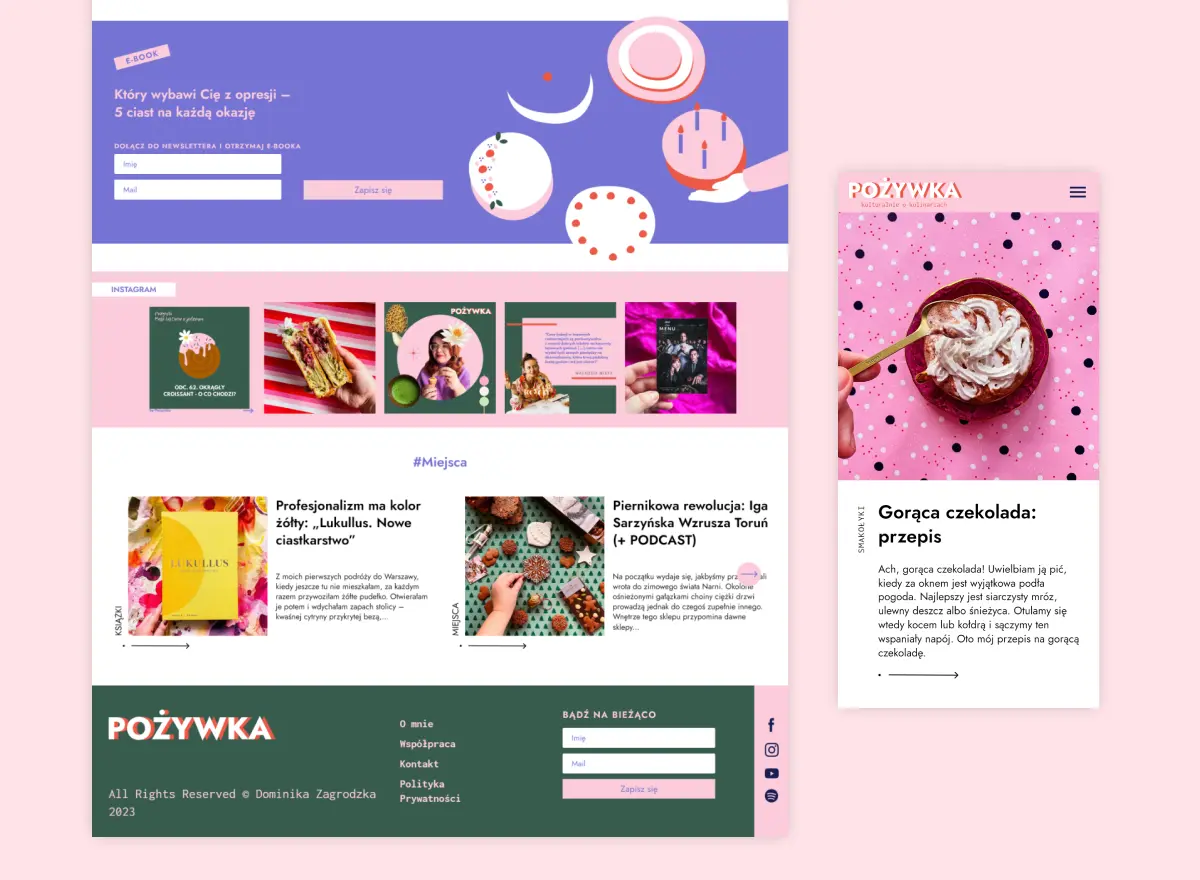
pozywka.pl
Scalable blog for food journalist, focused on performance and user experience 🌭
zagrodzki.me
Personal blog and portfolio of Bart Zagrodzki, where he shares his knowledge and work 💼
TurboStarter
Ship your startup everywhere. In minutes.
HTML to Markdown
Convert HTML to Markdown with ease, directly in your browser 📄
Dotallio
Personalized AI apps that automate research, data extraction, and content creation without code 🤖
Talk to Santa
Enjoy a magical live video chat or receive a unique AI-generated video greeting from Santa Claus 🎅
pozywka.pl
Scalable blog for food journalist, focused on performance and user experience 🌭
zagrodzki.me
Personal blog and portfolio of Bart Zagrodzki, where he shares his knowledge and work 💼
TurboStarter
Ship your startup everywhere. In minutes.
HTML to Markdown
Convert HTML to Markdown with ease, directly in your browser 📄
Omichat
Chat with 50+ AI models, including ChatGPT and Claude, in one place - switch models anytime without losing context 🤖
Claude Fast
Supercharge your Claude Code with 6x effective context window and specialized AI agents 🤖
EmojAI
AI-powered emoji picker with smart, context-aware suggestions 🤖
Solohacker
Autonomous company launcher - AI agents work 24/7, escalate what matters, and you stay in control 🤖
BeRawi: Storytelling Coach
Practice storytelling daily with instant feedback to sound clearer, more engaging, and confident 🎤
Omichat
Chat with 50+ AI models, including ChatGPT and Claude, in one place - switch models anytime without losing context 🤖
Claude Fast
Supercharge your Claude Code with 6x effective context window and specialized AI agents 🤖
EmojAI
AI-powered emoji picker with smart, context-aware suggestions 🤖
Solohacker
Autonomous company launcher - AI agents work 24/7, escalate what matters, and you stay in control 🤖
BeRawi: Storytelling Coach
Practice storytelling daily with instant feedback to sound clearer, more engaging, and confident 🎤
Connect with like-minded people
Join our community to get feedback, support, and grow together with 1,000+ builders on board, let's ship it!
Join usShip your startup everywhere. In minutes.
Don't burn tokens on setup and start building features on day one.